The Bit Bucket

SSMS: Dragging all column names from Object Explorer

SSMS: Dragging all column names from Object Explorer

This is a really popular shortcut in SQL Server Management Studio (SSMS) but I continue to be amazed how many people aren’t aware of it.

Object Explorer is a very useful part of SSMS and you can drag pretty much any name that you see in it, across to a query window.
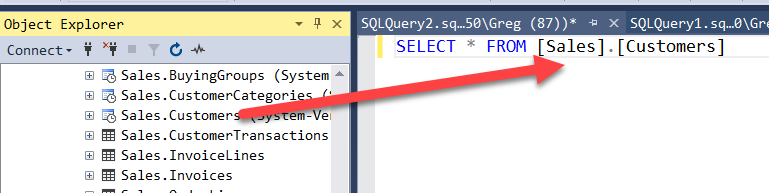
You could do the same for each column in the Columns list.

You might also realize that you can hover over the asterisk and see a list of columns:

2017-11-09
SDU Tools: Translate

SDU Tools: Translate

I love it when SQL Server gets brand new T-SQL language features.

SQL Server 2017 added a great new language feature called TRANSLATE. It’s been in some other products like Oracle for a while but it’s just been added to SQL Server.

image

Imagine I have a string like this:

’[02] 9992:2343’ 

But what I really want is one like this:

’(02) 9992-2343’

Up to SQL Server 2016, I could do this with a series of replace statements:

2017-11-08

Opinion: ORMs: Are they a good idea when developing for SQL Server?

Opinion: ORMs: Are they a good idea when developing for SQL Server?

Many people know that I have an issue with ORMs (object relational mappers). It’s worth spending a blog post to describe why.

Unfortunately, I spend my life on the back end of trying to deal with the messes involved. The following are the key issues that I see:

Potentially horrid performance

image

I’ve been on the back end of this all the time. There are several reasons. One is that the frameworks generate horrid code to start with, the second is that they are typically quite resistant to improvement, the third is that they tend to encourage processing with far too much data movement.

2017-11-07

SDU Tools: Empty Schema

SDU Tools: Empty Schema

Occasionally I run into a need to clear out all objects in a schema in a SQL Server database. Sometimes it’s because I want to remove the schema itself. It’s often painful to do as I have to find all the types of T-SQL objects, and then often have to remove them in a particular order.

So I added a tool to my SDU Tools collection to do just that.

2017-11-03

SDU Tools: Invert String in T-SQL

SDU Tools: Invert String in T-SQL

I recently shipped the latest update to my SDU Tools collection.

This time I decided to add a tool that’s in the “cute” category. It’s called InvertString and you can see it action in the image above.

Yes, it takes an input string and returns a string that looks quite like an upside down version of the same string.

As part of the inversion I also reversed the order of the string so when you look at it upside down, it still looks correct. But if what you really want is a mirror image, you could combine it with REVERSE to achieve that outcome:

2017-10-31

SQL: NEWSEQUENTIALID - Nice try but missed the target

SQL: NEWSEQUENTIALID - Nice try but missed the target

GUIDs (uniqueidentifiers in SQL Server) are well understood to cause fragmentation issues when used as clustering keys for SQL Server tables. It’s easy to understand why, but is NEWSEQUENTIALID the answer? I don’t think so. Here’s why.

When a SQL Server table has a clustered index, it needs to maintain the logical sequence of rows in the order of the clustering key. There are a few important notes here:

  • I’ve mentioned key, not column. The key might involve more than one column.
  • I’m not talking about primary keys. While the default for SQL Server is to make primary keys clustered if there isn’t already another clustering key, primary keys are a logical construct unrelated to how the table data is stored.
  • I’m not talking about physical storage. I often hear people say that clustered indexes determine how data is physically stored. That was in old Microsoft courseware, etc. and just isn’t true. It’s about logical ordering. If not, there would be no fragmentation and changing the data would take forever.
  • The problem with using GUIDs as clustering keys is that they are typically generated in a random order using a function like NEWID() or using a function like System.Guid.NewGuid() in .NET (or similar functions in other languages).

Let’s take a look at this by creating a table and populating it:

2017-10-26

SQL: What's in a name? How should SQL Server 2017 Graph Edge tables be named?

SQL: What's in a name? How should SQL Server 2017 Graph Edge tables be named?

Dennes Torres recently wrote a really excellent article introducing Graph Objects in SQL Server 2017. You’ll find it at Simple Talk.

I’ve also recently published a SQL Down Under podcast with Shreya Verma from the SQL Server team, where we discussed Graph extensions to SQL Server. (It’s part of a joint interview. We also discussed Adaptive Query Plans with Joe Sack). You’ll find that here: https://sqldownunder.com/podcast

I loved Dennes’ article but one aspect that I want to talk a little more about is the naming of Edge tables. As I read the article, I was a little troubled about the edge naming. (Let me stress that it’s a very, very minor item in a very good article and just my opinion).

2017-07-10

SDU Tools: More free SQL Server developer and DBA tools: May SDU Tools Release

SDU Tools: More free SQL Server developer and DBA tools: May SDU Tools Release

Hi Folks,

We’ve just created the May 2017 update for SDU Tools. We’re pretty excited about what we’re delivering this month.

The first part that we’ve added is a set of tools to make it really, really easy to capture a performance query trace, to load it, and to perform a basic analysis of it. There are three tools involved in this:

  • CapturePerformanceTuningTrace – Just give the trace a name, say where it should be stored, which databases to filter on (if any), and how long you want the trace to run. We do the rest.
  • LoadPerformanceTuningTrace – This tool loads the completed trace into a table.
  • AnalyzePerformanceTuningTrace - And then we find the things in the trace that are of interest – automatically

Next, we’ve added a useful tool to help with your database consistency. I often run into databases where columns that hold the same information are defined differently across the database.

2017-05-07

Avoiding invalid object name errors with temporary tables for BizTalk, Reporting Services and apps using SET FMTONLY

Avoiding invalid object name errors with temporary tables for BizTalk, Reporting Services and apps using SET FMTONLY

When applications need to call stored procedures, they try to work out what the returned data will look like ie: which columns come back, what data types are they, etc.

The old way of doing this was to call SET FMTONLY ON. Unfortunately, many applications like Biztalk and versions of Reporting Services still did this, and/or still do this. The same issue happens with Linq to SQL and other tools that use SQL Metal.

2017-04-11